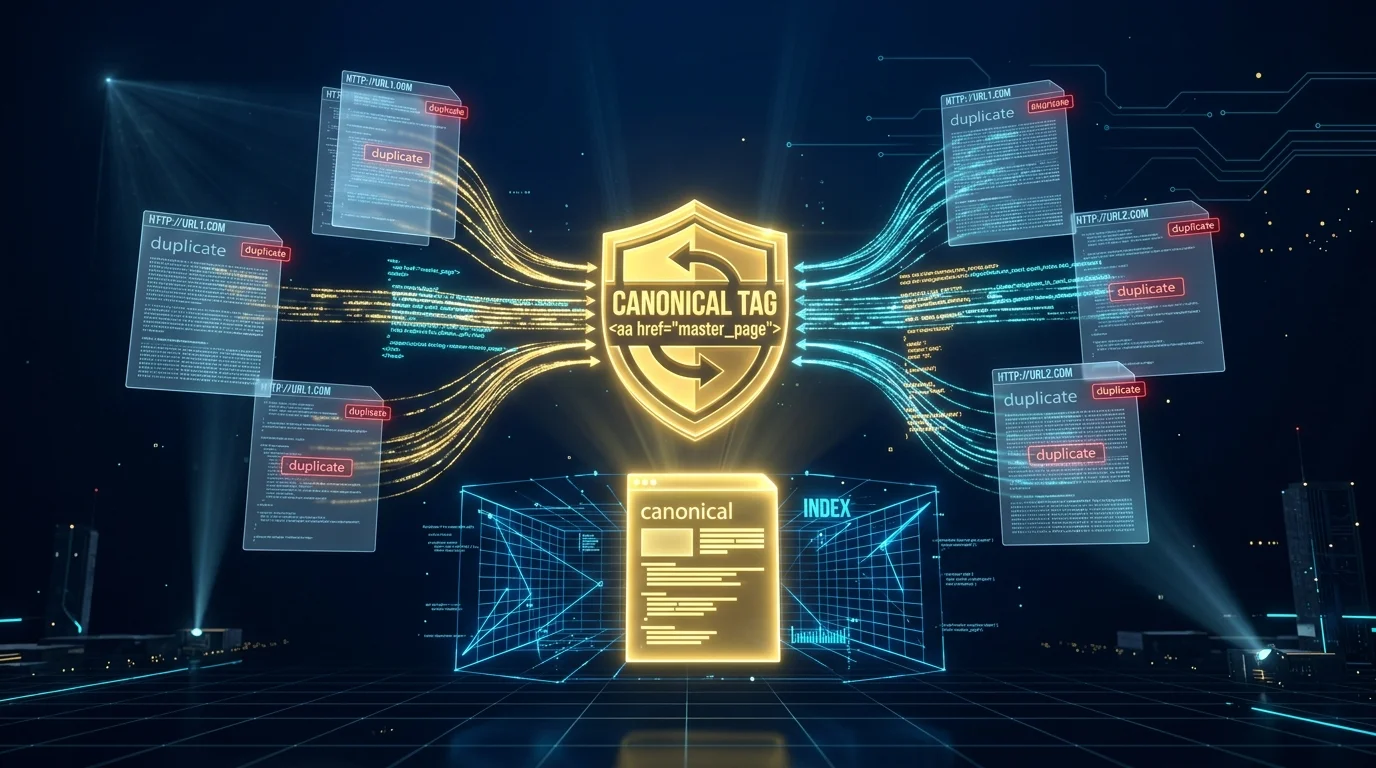
Duplicate content is one of the most widely misunderstood phenomena in search engine optimization. For over two decades, digital marketers have repeated the persistent myth of the dreaded "Google duplicate content penalty," imagining an automated algorithmic guillotine ready to wipe an entire domain off search results for publishing repeated text. Yet, official search documentation and senior Google engineers have consistently clarified that no such negative manual penalty exists for standard editorial or technical duplication.
However, the absence of an explicit punitive penalty does not mean duplicate content is harmless. In reality, duplicate and near-duplicate content triggers severe structural friction across search engine crawling, indexation, PageRank distribution, and ranking algorithms. When identical or substantially similar blocks of copy exist across multiple URLs on your domain (internal duplicate content) or across independent websites (external duplicate content), search engines are forced to deploy algorithmic filters. Instead of indexing and evaluating every variant, Google's indexer groups identical documents into clusters, designates a single "canonical" URL to represent the cluster, and simply filters out the rest from search engine results pages (SERPs).
The real operational danger of duplicate content is not an algorithmic penalty—it is inefficiency, authority fragmentation, and commercial misdirection. It fractures inbound backlink equity, bleeds valuable crawl budget on bloated enterprise architectures, induces ranking volatility, and often causes search engines to rank an irrelevant, non-converting technical variant rather than your flagship commercial service page. Furthermore, in the modern era of Generative AI, Retrieval-Augmented Generation (RAG), and Google AI Overviews, duplicate content fails Google’s strict Information Gain scoring thresholds, locking unoriginal websites out of generative answers entirely.
In this definitive guide, our senior technical search engineers at Professional SEO Services break down every operational nuance of duplicate content. You will explore Google's underlying mathematical deduplication mechanisms (including SimHash and MinHash document fingerprinting), dismantle the penalty myth, analyze internal versus external duplication vectors, resolve complex ecommerce faceted navigation challenges, protect against scrapers, examine the impact on AI Search, and execute an enterprise-grade remediation playbook. For businesses seeking a comprehensive technical diagnosis, explore our dedicated Technical SEO services or request a bespoke structural audit.
Table of Contents
- What Exactly Is Duplicate Content in SEO?
- How Google Handles Duplicate Content: Deduplication Architecture
- The "Duplicate Content Penalty" Myth vs. Algorithmic Reality
- 5 Concrete Ways Duplicate Content Destroys Organic Performance
- Internal vs. External Duplicate Content: Causes & Mechanics
- What Percentage of Duplicate Content Is Acceptable?
- The Information Gain Patent, AI Overviews & LLM Semantic Deduplication
- Duplicate Content vs. Keyword Cannibalization: What Is the Difference?
- The Ecommerce Duplicate Content Playbook: Facets, Variants & Manufacturer Specs
- International SEO: Multi-Regional English Sites, Hreflang & Canonicals
- Scraper Defense: What to Do When Third Parties Steal Your Content
- How to Detect Duplicate Content: Diagnostic Audit Workflows
- How to Fix Duplicate Content: The Decision Matrix & Technical Directives
- Frequently Asked Questions (FAQ)
What Exactly Is Duplicate Content in SEO?
According to official Google Search Central documentation, duplicate content generally refers to substantive blocks of content within or across domains that either completely match other content or are remarkably similar in wording and semantic meaning.
In technical terms, duplicate content is categorized into two distinct linguistic formats:
- Exact-Match (True) Duplication: Identical byte-for-byte or word-for-word textual documents served across multiple discrete URLs. For instance, accessing a page via
https://example.com/blog/seo/versushttps://example.com/blog/seo/?utm_source=linkedinorhttp://example.com/blog/seo. - Near-Duplicate Content: Pages that share 80% to 95% identical copy, layout structure, and semantic entities, differing only by minor geographical tokens, swapped product names, or trivial introductory phrases. Common examples include localized service pages (e.g., "Plumber in Manchester" vs. "Plumber in Bolton") where only city names are altered, or ecommerce category pages with identical products displayed under different sorting orders.
Crucially, duplicate content is not an intentional act of malice on the vast majority of websites. In more than 90% of technical audits, duplication stems from default CMS configurations, tracking parameter generation, faceted navigation architecture, or staging environment indexation.
How Google Handles Duplicate Content: Deduplication Architecture
To understand how duplicate content impacts rankings, one must examine the computational physics of search engine indexation. Processing billions of web pages daily requires petabytes of compute, storage, and electricity. Search engines like Google cannot afford to store, render, and rank duplicate copies of the same digital asset.
Google handles duplicate content through a sophisticated multi-stage deduplication pipeline:
1. Document Fingerprinting & Shingling (SimHash / MinHash)
When Googlebot retrieves a document's HTML, the Caffeine indexing pipeline strips boilerplate scaffolding and analyzes the primary content block (Main Content, or MC). The text is converted into n-grams (shingles)—small overlapping sequences of words. Using hashing algorithms such as SimHash and MinHash, Google generates a compact 64-bit fingerprint vector representing the semantic contents of the document.
By calculating the Hamming distance between document fingerprints, Google's indexer can instantly determine whether two distinct URLs represent duplicate or near-duplicate documents without performing expensive string-matching computations.
2. Cluster Formation
When multiple URLs yield identical or near-identical fingerprints, Google groups them into an internal Duplicate Cluster. Rather than treating each URL as an independent candidate document for ranking, the search engine treats the entire cluster as a single logical entity.
3. Canonical Representative Election
Within every duplicate cluster, Google must select exactly one URL to serve as the Canonical Representative. This representative URL is stored in the primary web index, displayed to searchers in SERPs, and credited with accumulated search signals. All other URLs in the cluster are folded into the canonical or suppressed from the primary index.
Google selects the canonical URL by evaluating a complex weighted matrix of internal and external signals:
- The
rel="canonical"Tag: The explicit annotation provided in the HTML<head>or HTTP header. - Internal Linking Signals: The URL that receives the highest volume of contextual internal links with descriptive anchor text across your site.
- XML Sitemap Inclusion: The specific URL version submitted in your authoritative
sitemap.xml. - Protocol & Security: Google strongly prefers secure HTTPS protocols over non-secure HTTP variants.
- URL Hygiene & Structure: Shorter, cleaner URLs without excessive URL parameters, session IDs, or redundant subfolder paths are prioritized.
- External Link Equity (PageRank): The URL that has accumulated the strongest backlink profile from authoritative external referring domains.
- Redirect Directives: Server-side 301 redirects signaling permanent consolidation.
The Canonical Hint Reality:
Google considers the rel="canonical" link tag an algorithmic hint, not an inviolable directive. If your canonical tag specifies URL A, but your internal navigation, breadcrumbs, XML sitemap, and external backlinks all point to URL B, Google's algorithms will systematically override your canonical tag and elect URL B as the primary version.
The "Duplicate Content Penalty" Myth vs. Algorithmic Reality
One of the most persistent anxieties expressed on forums like Reddit’s r/SEO is: "Will Google issue a manual penalty and deindex my website if I have duplicate content?"
The short, definitive answer is no. Google does not have a specific "duplicate content penalty" that punishes normal websites for having repetitive text.
Google’s official Search Quality team, as well as Developer Advocates like John Mueller and Gary Illyes, have repeatedly reiterated:
"Duplicate content on a site is not grounds for action on that site unless it appears that the intent of the duplicate content is to be deceptive and manipulate search engine results... There is no duplicate content penalty. In the worst case, we pick one version and show that."
— Google Search Central Guidelines
The only scenario where Google issues a Manual Action (penalty) for duplication is when a website engages in deceptive manipulation or automated abuse, such as:
- Malicious Scraper Networks: Automated domains scraping RSS feeds and republishing copyrighted content without adding any unique context or editorial commentary.
- Spammy Programmatic Thin Pages: Spinning hundreds of identical doorway pages designed exclusively to game local queries or capture affiliate clicks.
- Cloaking & Sneaky Redirects: Serving one set of duplicate content to search engine bots while serving deceptive affiliate or malware payloads to human visitors.
For everyday publishers, ecommerce retailers, and service providers, duplicate content is treated strictly as an algorithmic filtering problem. If you want to understand how real algorithmic and manual actions function, read our comprehensive investigation on what is a Google penalty in SEO.
5 Concrete Ways Duplicate Content Destroys Organic Performance
While there is no punitive penalty, duplicate content inflicts profound commercial and architectural damage on organic performance. When left unresolved, duplicate content undermines search visibility through five distinct mechanisms:
1. Severe Dilution of Backlink Equity (PageRank Fragmentation)
Backlinks remain one of Google's top foundational ranking signals. However, link equity (historically measured as PageRank) flows to specific URLs, not vague abstract concepts.
If an external publication links to https://example.com/product, while an influencer shares https://example.com/product?ref=social, and a directory links to http://www.example.com/product/, your domain's earned backlink equity is fractured across three distinct endpoints. Instead of compounding link authority into a single powerhouse page capable of outranking competitors in the top three positions, your authority is divided into three weak, mediocre signals.
2. Crawl Budget Exhaustion on Enterprise & Ecommerce Architectures
Search engines do not possess infinite time or resources to crawl a domain. Google assigns every site a Crawl Budget, governed by Crawl Rate Limit (server capacity) and Crawl Demand (site popularity and freshness). According to Google's Large Site Crawl Budget Guide, faceted navigation and duplicate URLs are the single largest source of crawl waste on the web.
When Googlebot spends 60% of its daily crawl allocation navigating through redundant URL parameters, session IDs, tracking strings, and paginated sorting variations, it has no remaining bandwidth to discover your newly published blog posts, updated inventory, or high-margin service landing pages. This leads to delayed indexation and stalled organic momentum. For enterprise stores, resolving these bottlenecks requires specialized Ecommerce SEO services.
3. SERP Demotion & Filtering (The Host Crowding Filter)
Google’s core mission is to provide diverse, helpful results. If multiple URLs on your site compete with near-identical copy, Google's algorithms apply deduplication filtering. Google will display only one version in the primary SERP and tuck the rest away behind the infamous message:
If Google filters your URLs, your secondary pages lose 100% of their organic impression share and traffic potential.
4. Commercial Misdirection (Ranking the Wrong URL)
When search algorithms are left to guess which URL is the canonical authority, they frequently choose the wrong page. For example, if you maintain a commercial landing page for On-Page SEO services, but also publish a printer-friendly version or an introductory checklist containing large excerpts of that same text, Google may algorithmically elect the checklist or printer page.
When searchers land on a stripped-down, unstyled technical variant with no conversion elements, clear calls-to-action (CTAs), or interactive calculators, bounce rates soar and valuable commercial revenue is permanently lost.
5. Index Bloat & Depressed Site-Wide Quality Scores
Since the introduction of Google's Helpful Content System (now integrated into the core ranking algorithm), Google evaluates a website's overall topical quality on a site-wide basis. If 70% of the URLs indexed on your domain consist of redundant, thin, or duplicate pages (such as empty tag archives, filtered facet combinations, or boilerplate duplicates), Google's holistic quality classifiers may deem your entire domain low-utility.
This site-wide drag suppresses the ranking capability of even your best, highest-quality editorial pieces. Maintaining strict content hygiene and reviewing an on-page SEO checklist is essential to protecting domain health.
Internal vs. External Duplicate Content: Causes & Mechanics
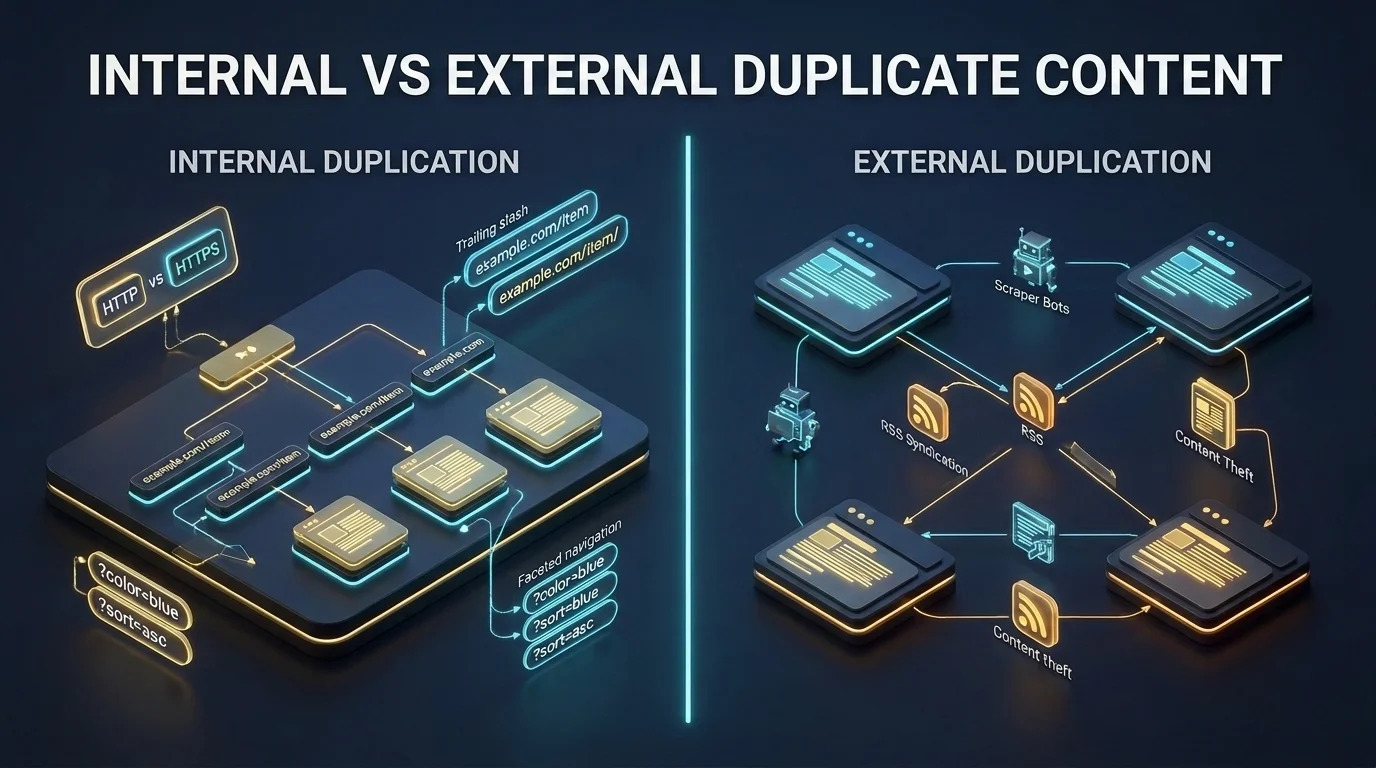
To formulate an effective remediation strategy, SEO architects must separate duplication into internal and external operational vectors:
Internal Duplicate Content Triggers
| Duplication Trigger | Technical Cause | Typical URL Example |
|---|---|---|
| Protocol Inconsistency | Server allows both HTTP and HTTPS versions to resolve without redirecting. | http://site.com/ vs https://site.com/ |
| Subdomain Redundancy | Both WWW and non-WWW hostnames return HTTP 200 OK status codes. | https://www.site.com/ vs https://site.com/ |
| Trailing Slash Variance | Server treats URLs with and without trailing slashes as distinct documents. | /blog/technical-seo vs /blog/technical-seo/ |
| Faceted Navigation | Ecommerce filters (size, color, brand, price) create exponential URL parameter variations. | /shoes/running?color=blue&sort=price_asc |
| Session IDs & UTM Tracking | Internal links mistakenly include analytics query strings or user session tokens. | /service?utm_source=internal_banner |
| CMS Taxonomy Archives | WordPress tag archives, date archives, and author archives repeating full article excerpts. | /tag/seo-tips/ vs /category/search-engine-optimization/ |
External Duplicate Content Triggers
- Content Syndication: Distributing your thought-leadership articles to third-party industry portals, LinkedIn Pulse, or Medium without enforcing cross-domain canonical links pointing back to your original URL.
- Manufacturer Product Descriptions: Utilizing standard copy provided by brand suppliers across thousands of independent retailer websites.
- Scraper Bots & Content Theft: Automated rogue web scrapers copying your content and republishing it on secondary domains to capture search traffic or sell programmatic ads.
- Staging & Dev Environments: Leaving test environments (e.g.,
staging.example.comordev.example.com) accessible to search crawlers without password protection ornoindexheaders.
What Percentage of Duplicate Content Is Acceptable?
A ubiquitous query raised in search forums is: "What is the maximum allowed duplicate percentage? Is 15% duplicate content okay? What about 30%?"
The reality of search engine architecture is that Google does not use a rigid percentage cutoff. Google does not say: "Any page with more than 20% duplicate text is filtered."
Instead, Google’s rendering engine segments HTML documents into structural functional blocks:
- Boilerplate / Supplementary Content (SC): Global header menus, navigation links, sidebar widgets, footer text, copyright statements, privacy policy links, and legal disclaimers. Search engines expect this copy to be 100% identical across every page on your website.
- Main Content (MC): The unique editorial core of the page—the article text, unique product specifications, case study findings, or specialized pricing tables.
Google’s deduplication algorithms evaluate the Main Content (MC) block. If your page features 3,000 words of boilerplate surrounding a thin 40-word paragraph identical to 50 other pages, that page provides near-zero unique value. Conversely, if your page features 1,500 words of deeply researched original analysis, having an identical 300-word corporate footer will never cause duplicate content issues.
The Information Gain Patent, AI Overviews & LLM Semantic Deduplication
The conversation surrounding duplicate content underwent a seismic shift with the introduction of modern Large Language Models (LLMs) and Google's Information Gain Scoring patent.
Google's Information Gain Patent (US Patent 10,698,975 B1)
Granted to Google, the patent titled "Contextual Estimation of Information Gain" describes an algorithmic framework designed to measure whether a web document provides novel information beyond what a user has already encountered across previously visited documents on the same topic.
Historically, websites could rank by summarizing existing search results—regurgitating the top 5 articles with slightly rewritten phrasing. Today, Google's algorithms analyze document vectors. If your article repeats the same consensus definitions, same bullet points, and same surface-level conclusions already present on competitor sites like StudioHawk or The SEO Works, your document receives an Information Gain score of zero.
In Google’s current Core Algorithm, zero-information-gain content is systematically demoted or excluded from search results, even if it is technically "unique" from a strict plagiarism checker perspective. To win in modern search, you must publish original data, case studies, proprietary frameworks, and counter-intuitive insights. Read more in our strategic analysis on content strategy and topical authority.
Semantic Deduplication in AI Search (Google AI Overviews, ChatGPT & Perplexity)
How does duplicate content affect Generative Search Engines and Retrieval-Augmented Generation (RAG) pipelines?
When an AI engine processes an informational query, it executes a three-stage pipeline:
- Document Retrieval: The system fetches candidate text passages from top-ranking indexed pages.
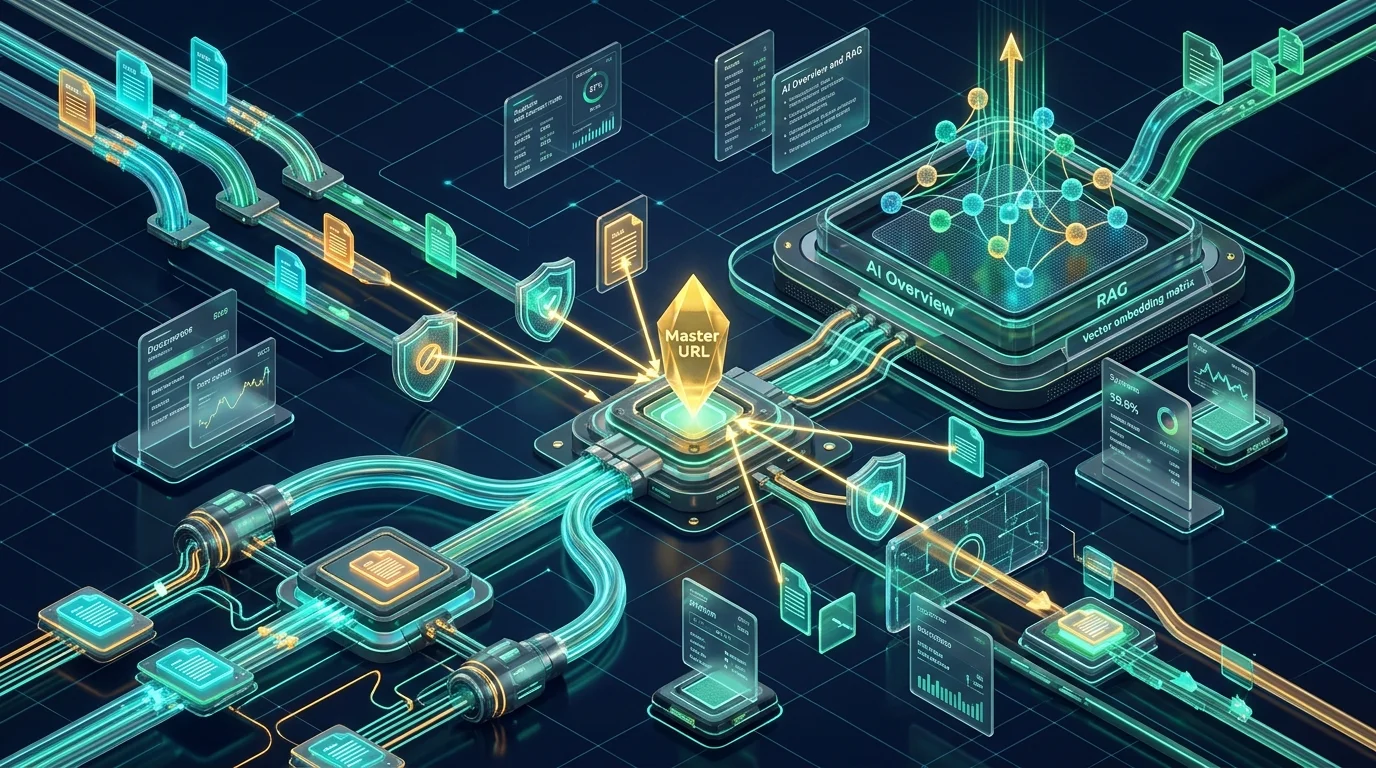
- Vector Embedding & Cosine Deduplication: Text passages are converted into high-dimensional mathematical vector embeddings. The system computes the cosine similarity between candidate chunks. If two or more chunks share a similarity score above a strict threshold (e.g., > 0.92), the pipeline immediately discards the duplicate chunks to prevent redundancy in the context window.
- LLM Synthesis & Citation: The generative model synthesizes the answer exclusively from the remaining non-redundant, high-information-gain text chunks, citing only those sources.
If your content merely duplicates or paraphrases competitor pages, it is filtered out at Stage 2. Duplicate content guarantees that your domain will never be cited in Google AI Overviews, ChatGPT Search, or Perplexity answers. Modern visibility requires specialized GEO, LLM & AI SEO services.
Duplicate Content vs. Keyword Cannibalization: What Is the Difference?
Search marketers frequently conflate duplicate content with keyword cannibalization. While both issues cause algorithmic confusion and volatile rankings, their underlying root causes are fundamentally different:
| Comparison Dimension | Duplicate Content | Keyword Cannibalization |
|---|---|---|
| Core Problem | Identical or near-identical text blocks existing across multiple URL endpoints. | Multiple completely unique URLs competing for the same search query and user intent. |
| Content Similarity | Very high (90% - 100% match in words, syntax, or layout). | Often completely different text, angles, and wording, but targeting identical keywords. |
| Search Engine Action | Deduplication filtering: Google elects one canonical URL and excludes the rest from SERPs. | Ranking oscillation: Google alternates between URLs, depressing overall ranking positions. |
| Primary Fix | Technical canonicalization, 301 server redirects, or parameter consolidation. | Intent re-mapping, content merging, or clear topical differentiation. |
For an exhaustive breakdown of intent collision and URL hopping, explore our comprehensive technical masterclass on what is SEO cannibalization in SEO.
The Ecommerce Duplicate Content Playbook: Facets, Variants & Manufacturer Specs
Ecommerce stores are the most susceptible to duplicate content vulnerabilities. With large catalogs, dynamic filtering, and syndicated manufacturer data, a store with 5,000 physical products can inadvertently generate 500,000 indexable URLs.
1. Faceted Navigation & Filter Sprawl
Faceted navigation allows users to filter products by color, size, price, and rating. If every filter combination generates a crawlable, indexable URL (e.g., /mens-shoes?size=10&color=black&brand=nike), search bots become trapped in parameter loops, burning crawl budget on virtually identical product grids.
The Solution:
- Keep top-level, high-search-volume category and subcategory pages indexable (e.g.,
/mens-running-shoes/). - Self-canonicalize or apply
rel="canonical"pointing back to the primary category URL for filtered parameter variations. - For multi-facet combinations (e.g., filtering 2 or more attributes simultaneously), dynamically inject a
<meta name="robots" content="noindex, follow">tag or utilize AJAX/JavaScript filtering that does not mutate the crawlable URL path.
2. Product Variant URLs
When a product is sold in 6 different colors and 5 sizes, some CMS platforms (such as Shopify or Magento) create 30 individual product URLs sharing 98% identical copy.
The Solution: Select a single primary master product URL (e.g., /products/wireless-running-headphones). Allow users to toggle color and size variations via front-end client-side JavaScript or URL parameters, and enforce a strict rel="canonical" tag pointing directly to the master URL.
3. Syndicated Manufacturer Product Descriptions
If your online store sells consumer electronics, sporting goods, or auto parts, copying descriptions verbatim from the manufacturer catalog means your product page is identical to 200 competing retail domains.
Because established giants like Amazon, Walmart, or Currys possess far higher domain authority, Google will award them the canonical ranking position, rendering your product page invisible.
The Solution: Rewrite product descriptions to deliver unique value. Include hands-on usage tips, proprietary sizing guidelines, real customer FAQs, unboxing video embeds, and structured product specification tables.
International SEO: Multi-Regional English Sites, Hreflang & Canonicals
Global businesses that operate in multiple English-speaking territories (such as the UK, US, Canada, Australia, and New Zealand) frequently publish nearly identical product and service copy across different regional subfolders or Country-Code Top-Level Domains (ccTLDs), such as .co.uk and .com.
A major blunder made by webmasters is adding a cross-domain canonical tag pointing from the UK site to the US site:
<!-- On https://example.co.uk/services/ -->
<link rel="canonical" href="https://example.com/services/" />
This tells Google that the UK page should not exist in search results, effectively deindexing your UK domain in local British searches.
The Correct Implementation:
- Each regional page must feature a self-referencing canonical tag:
<link rel="canonical" href="https://example.co.uk/services/" /> - Pair the self-referencing canonical tag with bidirectional, reciprocal
hreflangannotations:<link rel="alternate" hreflang="en-gb" href="https://example.co.uk/services/" /> <link rel="alternate" hreflang="en-us" href="https://example.com/services/" /> <link rel="alternate" hreflang="en-au" href="https://example.com.au/services/" /> <link rel="alternate" hreflang="x-default" href="https://example.com/services/" />
The hreflang tag informs Google that the duplicate text is specifically intended for different regional audiences, instructing the search engine to serve the appropriate local URL without triggering deduplication filtering. For a deeper breakdown of domain structures, consult our guide on is .com or .co.uk better for SEO or explore our International SEO services.
Scraper Defense: What to Do When Third Parties Steal Your Content
A terrifying scenario shared frequently on Reddit’s SEO communities is discovering that an unprincipled third-party scraper has stolen your original article word-for-word, and Google is ranking the scraper above your own website!
Why does this happen? If the scraper domain possesses a higher Domain Rating, faster crawling frequency, or a cleaner backlink profile, Googlebot may crawl and index the scraped version before discovering your original URL, mistakenly establishing the scraper as the original source.
To defend your domain and recover your rankings, execute this 4-step scraper defense protocol:
- Verify Self-Referencing Canonicals & Structured Data: Ensure every published article features a self-referencing
rel="canonical"tag and detailedBlogPostingJSON-LD schema with complete author attribution (e.g., Rehan Saeed) and an ISO 8601 published date stamp. Many amateur scraper bots copy HTML verbatim, inadvertently scraping your canonical tag and crediting your URL! - Use Absolute Internal Links: Always code internal hyperlinks using absolute URLs (e.g.,
https://www.professionalseoservices.uk/services/technical-seo/) rather than relative paths (e.g.,/services/technical-seo/). When scrapers syndicate your text, their site will inadvertently generate direct, high-value backlinks pointing back to your domain. - Force Googlebot Re-Crawl via Search Console: Immediately upon publishing any high-value content, submit the URL inside Google Search Console’s URL Inspection tool and request indexing. This establishes your timestamp in Google’s index before scrapers have an opportunity to discover your RSS feed.
- File a Formal DMCA Takedown Notice: If a scraper outranks you and refuses to remove the content, submit an official DMCA removal request directly to Google via the Google Copyright Removal Dashboard. Simultaneously, identify the scraper's web host using tools like WhoIsHostingThis and file a copyright complaint with their abuse department.
How to Detect Duplicate Content: Diagnostic Audit Workflows
Before deploying technical fixes, search engineers must perform comprehensive diagnostic audits across multiple specialized toolsets:
1. Google Search Console Diagnostics
- Navigate to Pages (under Indexing).
- Inspect the status report: "Duplicate without user-selected canonical". These are URLs where Google detected duplicate content and chose a canonical URL on your behalf because you failed to specify one.
- Inspect the status report: "Duplicate, Google chose different canonical than user". This is an urgent red flag indicating that Google disagreed with your
rel="canonical"tag, overriding your instruction and selecting an alternative URL.
2. Screaming Frog SEO Spider Audits
- Launch an enterprise crawl of your domain.
- Navigate to the Content tab in the right-hand panel.
- Review the Exact Duplicates filter: Displays pages with identical MD5 algorithm hash values.
- Review the Near Duplicates filter: Identifies pages sharing 90% or higher similarity based on text shingling algorithms.
- Navigate to the Canonicals tab and filter by "Canonicaliser Error" or "Missing Canonical".
3. Advanced Google Search Operators
To quickly verify whether Google is filtering specific passages on your site, copy a unique 15-word sentence from your primary article and paste it into Google search enclosed in double quotes:
If Google returns multiple URLs from your domain, you have an immediate internal duplicate content overlap. If Google returns third-party domains, you have identified external scrapers.
How to Fix Duplicate Content: The Decision Matrix & Technical Directives
Remediating duplicate content requires choosing the correct architectural tool for each specific technical scenario. Applying the wrong directive can inadvertently deindex high-value commercial assets.
The Duplicate Content Remediation Decision Matrix
| Technical Scenario | Recommended Action | Implementation Mechanism |
|---|---|---|
| HTTP vs HTTPS / WWW vs Non-WWW | 301 Permanent Redirect | Server-level rewrite rules (.htaccess / Nginx / Cloudflare). |
| Trailing Slash Redundancy | 301 Permanent Redirect | Enforce uniform trailing slash standard across web server config. |
| Ecommerce Product Variants (Color/Size) | rel="canonical" Tag |
Point variant pages to the primary master product URL. |
| Marketing Tracking URLs (UTMs / Affiliates) | rel="canonical" Tag |
Point parameter URLs to the clean canonical root path. |
| Internal Search Results Pages | noindex, follow Tag |
Robots meta tag to prevent low-quality internal search bloat. |
| Third-Party Syndicated Articles | Cross-Domain Canonical | Syndicating partner points rel="canonical" to your original post. |
| Multi-Regional Localized Sites | Self-Canonical + Hreflang | Self-referencing canonical paired with reciprocal hreflang annotations. |
| Old, Redundant or Deprecated Content | Content Merge + 301 Redirect | Merge unique insights into primary master URL, 301 redirect old URL. |
Why You Should NEVER Use Robots.txt to Fix Duplicate Content Indexing
One of the most dangerous misconceptions in technical SEO is using robots.txt to disallow duplicate URLs.
A robots.txt file is a crawl directive, not an indexation directive. If you disallow a duplicate URL via robots.txt, search bots are blocked from crawling the page. Consequently:
- Googlebot cannot read the
rel="canonical"tag on the page. - Googlebot cannot read a
noindexrobots meta tag. - If the duplicate URL has incoming external backlinks or internal links, Google will still index the bare URL without snippets, creating an unsightly and index-bloated search result!
To allow canonical tags and 301 redirects to pass PageRank and consolidate authority, Googlebot must be allowed to crawl the duplicate URL. For a detailed guide on handling site health and error codes, read are 404s bad for SEO.
Technical Code Implementations
1. Implementing a Server-Level 301 Redirect (.htaccess for Apache):
RewriteEngine On

# Force HTTPS
RewriteCond %{HTTPS} off
RewriteRule ^(.*)$ https://%{HTTP_HOST}%{REQUEST_URI} [L,R=301]

# Force non-WWW (or WWW depending on preferred canonical version)
RewriteCond %{HTTP_HOST} ^www\.(.*)$ [NC]
RewriteRule ^(.*)$ https://%1/$1 [R=301,L]

# Enforce Trailing Slash
RewriteCond %{REQUEST_FILENAME} !-f
RewriteCond %{REQUEST_URI} !(.*)/$
RewriteRule ^(.*)$ https://%{HTTP_HOST}/$1/ [L,R=301]
2. Implementing a Standard HTML Canonical Tag:
<!-- Place inside the <head> section of the duplicate or variant page -->
<link rel="canonical" href="https://www.professionalseoservices.uk/blog/how-does-duplicate-content-affect-seo/" />
3. Implementing HTTP Header Canonical for Non-HTML Documents (PDFs):
# Apache configuration for PDF whitepapers matching a blog URL
<Files "whitepaper-seo-guide.pdf">
  Header add Link '<https://www.professionalseoservices.uk/blog/technical-seo-guide/>; rel="canonical"'
</Files>
Frequently Asked Questions (FAQ)
Does Google have an official duplicate content penalty?
No. Google does not maintain a punitive penalty that penalizes regular websites for containing duplicate content. Unless content is generated through malicious scraper networks or doorway page spam designed to deceive search algorithms, Google handles duplication algorithmically by clustering identical URLs and selecting a single canonical URL to display in search results, simply filtering out the duplicates.
How does duplicate content negatively affect SEO if there is no penalty?
Even without a manual penalty, duplicate content damages organic performance by splitting backlink PageRank across multiple URLs, causing keyword and intent confusion, exhausting crawl budget on repetitive parameters, and diluting organic CTR. Furthermore, Google may index an unintended, non-converting technical variant rather than your flagship commercial service page.
What is the difference between internal and external duplicate content?
Internal duplicate content occurs when identical or substantially similar copy is accessible across multiple URLs on the same domain (e.g., HTTP vs. HTTPS, trailing slash variants, or faceted navigation filters). External duplicate content occurs across completely different domains, such as third-party syndication, partner republishing, or rogue scraper bots copying your editorial assets.
What percentage of duplicate content is considered acceptable?
There is no fixed percentage threshold enforced by search algorithms. Boilerplate elements like headers, footers, navigation bars, and legal disclaimers regularly constitute 20% to 40% of code across millions of pages without issue. Search engines evaluate the Main Content (MC) body block. As long as the primary editorial body provides unique information gain and original value, boilerplate repetition is ignored.
How does Google select the canonical URL among duplicate pages?
Google evaluates multiple weighted signals: the explicit rel="canonical" tag, internal linking architecture and anchor text, XML sitemap inclusion, protocol preference (HTTPS over HTTP), URL cleanliness and brevity, redirects, and incoming PageRank/backlink volume. If these signals conflict, Google's algorithms override the rel=canonical tag and choose the version they perceive as authoritative.
What should I do if a scraper steals my content and outranks me?
Verify that your original URL features a self-referencing rel="canonical" tag, is included in your XML sitemap, and is indexed with complete author entity schema. Ensure your body copy contains absolute internal links. Immediately submit new content via Google Search Console upon publication. If the scraper continues to outrank you, submit an official DMCA removal request through Google's Copyright Removal Dashboard.
Is a 301 redirect better than a rel=canonical tag?
A 301 redirect is stronger and more definitive than a canonical tag because it is an authoritative server-level instruction that forces crawlers and browsers to the destination URL, transferring virtually all link equity. A rel=canonical tag is an algorithmic hint that Google can ignore if the content on the two pages diverges. Use 301 redirects when the duplicate page does not need to exist for users, and rel=canonical when duplicate variations must remain active for user experience.
Does duplicate content affect crawl budget?
Yes, especially for large enterprise and ecommerce websites with tens of thousands of URLs. When search bots spend their allocated crawl demand and crawl rate crawling faceted filter combinations, tracking parameters, and duplicate URLs, they have fewer resources to crawl, render, and index new products or recently updated high-value content.
How does duplicate content impact AI search engines like ChatGPT and Google AI Overviews?
Modern Large Language Models (LLMs) and Retrieval-Augmented Generation (RAG) pipelines convert text into vector embeddings and apply semantic cosine deduplication during chunk retrieval. Content that repeats existing consensus text without offering novel data, original analysis, or unique entity relationships receives a low Information Gain score and is filtered out before AI Overviews or answer summaries are generated.
How do you handle duplicate content on international websites with multiple English regions?
When serving identical or localized English copy to different countries (e.g., US, UK, Australia, Canada), use correct hreflang annotations (e.g., en-us, en-gb, en-au) to tell search engines the intended geographic audience. Each localized URL should feature a self-referencing canonical tag paired with reciprocal hreflang tags, rather than cross-domain canonicalizing to a single country's version.
Final Takeaway: Turn Duplication Into Topical Authority
The fundamental truth of modern search architecture is simple: duplicate content does not trigger an automatic penalty, but it quietly sabotages organic performance by fracturing your domain's authority, wasting crawl budget, and suppressing click-through rates.
In an era dominated by semantic entity mapping, the Information Gain patent, and Generative AI Overviews, repeating consensus information is a guaranteed formula for organic invisibility. By resolving technical URL duplication through disciplined canonicalization and 301 redirects, and elevating your editorial copy with original data and proprietary insight, you transform a bloated, fragmented search footprint into a concentrated, authoritative topical fortress.
The 5-Stage Duplicate Content Remediation Protocol
Audit → Cluster → Elect Master URL → Consolidate (301 / Canonical) → Elevate Information Gain
If your enterprise suspects that legacy faceted navigation, URL parameter sprawl, or content overlap is capping your organic revenue potential, reach out to our senior engineering specialists at Professional SEO Services for a comprehensive SEO strategy audit. We engineer high-performance search architectures that eliminate algorithmic friction and drive compounding organic growth.